> ## Documentation Index
> Fetch the complete documentation index at: https://cubed3-pavel-claude-modest-planck-ceg4c0.mintlify.site/llms.txt
> Use this file to discover all available pages before exploring further.
# Lambda pre-aggregations
> Lambda-style pre-aggregations that merge historical rollups with fresher source or streaming layers for near-real-time serving on Cube Store.
Lambda pre-aggregations follow the
[Lambda architecture](https://en.wikipedia.org/wiki/Lambda_architecture) design
to union real-time and batch data. Cube acts as a serving layer and uses
pre-aggregations as a batch layer and source data or other pre-aggregations,
usually [streaming][streaming-pre-agg], as a speed layer. Due to this design,
lambda pre-aggregations **only** work with data that is newer than the existing
batched pre-aggregations.
Lambda pre-aggregations only work with Cube Store.
## Use cases
Below we are looking at the most common examples of using lambda
pre-aggregations.
### Batch and source data
Batch data is coming from pre-aggregation and real-time data is coming from the
data source.
First, you need to create pre-aggregations that will contain your batch data. In
the following example, we call it `batch`. Please note, it must have a
`time_dimension` and `partition_granularity` specified. Cube will use these
properties to union batch data with freshly-retrieved source data.
You may also control the batch part of your data with the `build_range_start`
and `build_range_end` properties of a pre-aggregation to determine a specific
window for your batched data.
Next, you need to create a lambda pre-aggregation. To do that, create
pre-aggregation with type `rollup_lambda`, specify rollups you would like to use
with `rollups` property, and finally set `union_with_source_data: true` to use
source data as a real-time layer.
Please make sure that the lambda pre-aggregation definition comes first when
defining your pre-aggregations.
```yaml title="YAML" theme={null}
cubes:
- name: users
# ...
pre_aggregations:
- name: lambda
type: rollup_lambda
union_with_source_data: true
rollups:
- CUBE.batch
- name: batch
measures:
- users.count
dimensions:
- users.name
time_dimension: users.created_at
granularity: day
partition_granularity: day
build_range_start:
sql: SELECT '2020-01-01'
build_range_end:
sql: SELECT '2022-05-30'
```
```javascript title="JavaScript" theme={null}
cube("users", {
// ...
pre_aggregations: {
lambda: {
type: `rollup_lambda`,
union_with_source_data: true,
rollups: [CUBE.batch]
},
batch: {
measures: [users.count],
dimensions: [users.name],
time_dimension: users.created_at,
granularity: `day`,
partition_granularity: `day`,
build_range_start: {
sql: `SELECT '2020-01-01'`
},
build_range_end: {
sql: `SELECT '2022-05-30'`
}
}
}
})
```
### Batch and streaming data
In this scenario, batch data is comes from one pre-aggregation and real-time
data comes from a [streaming pre-aggregation][streaming-pre-agg].
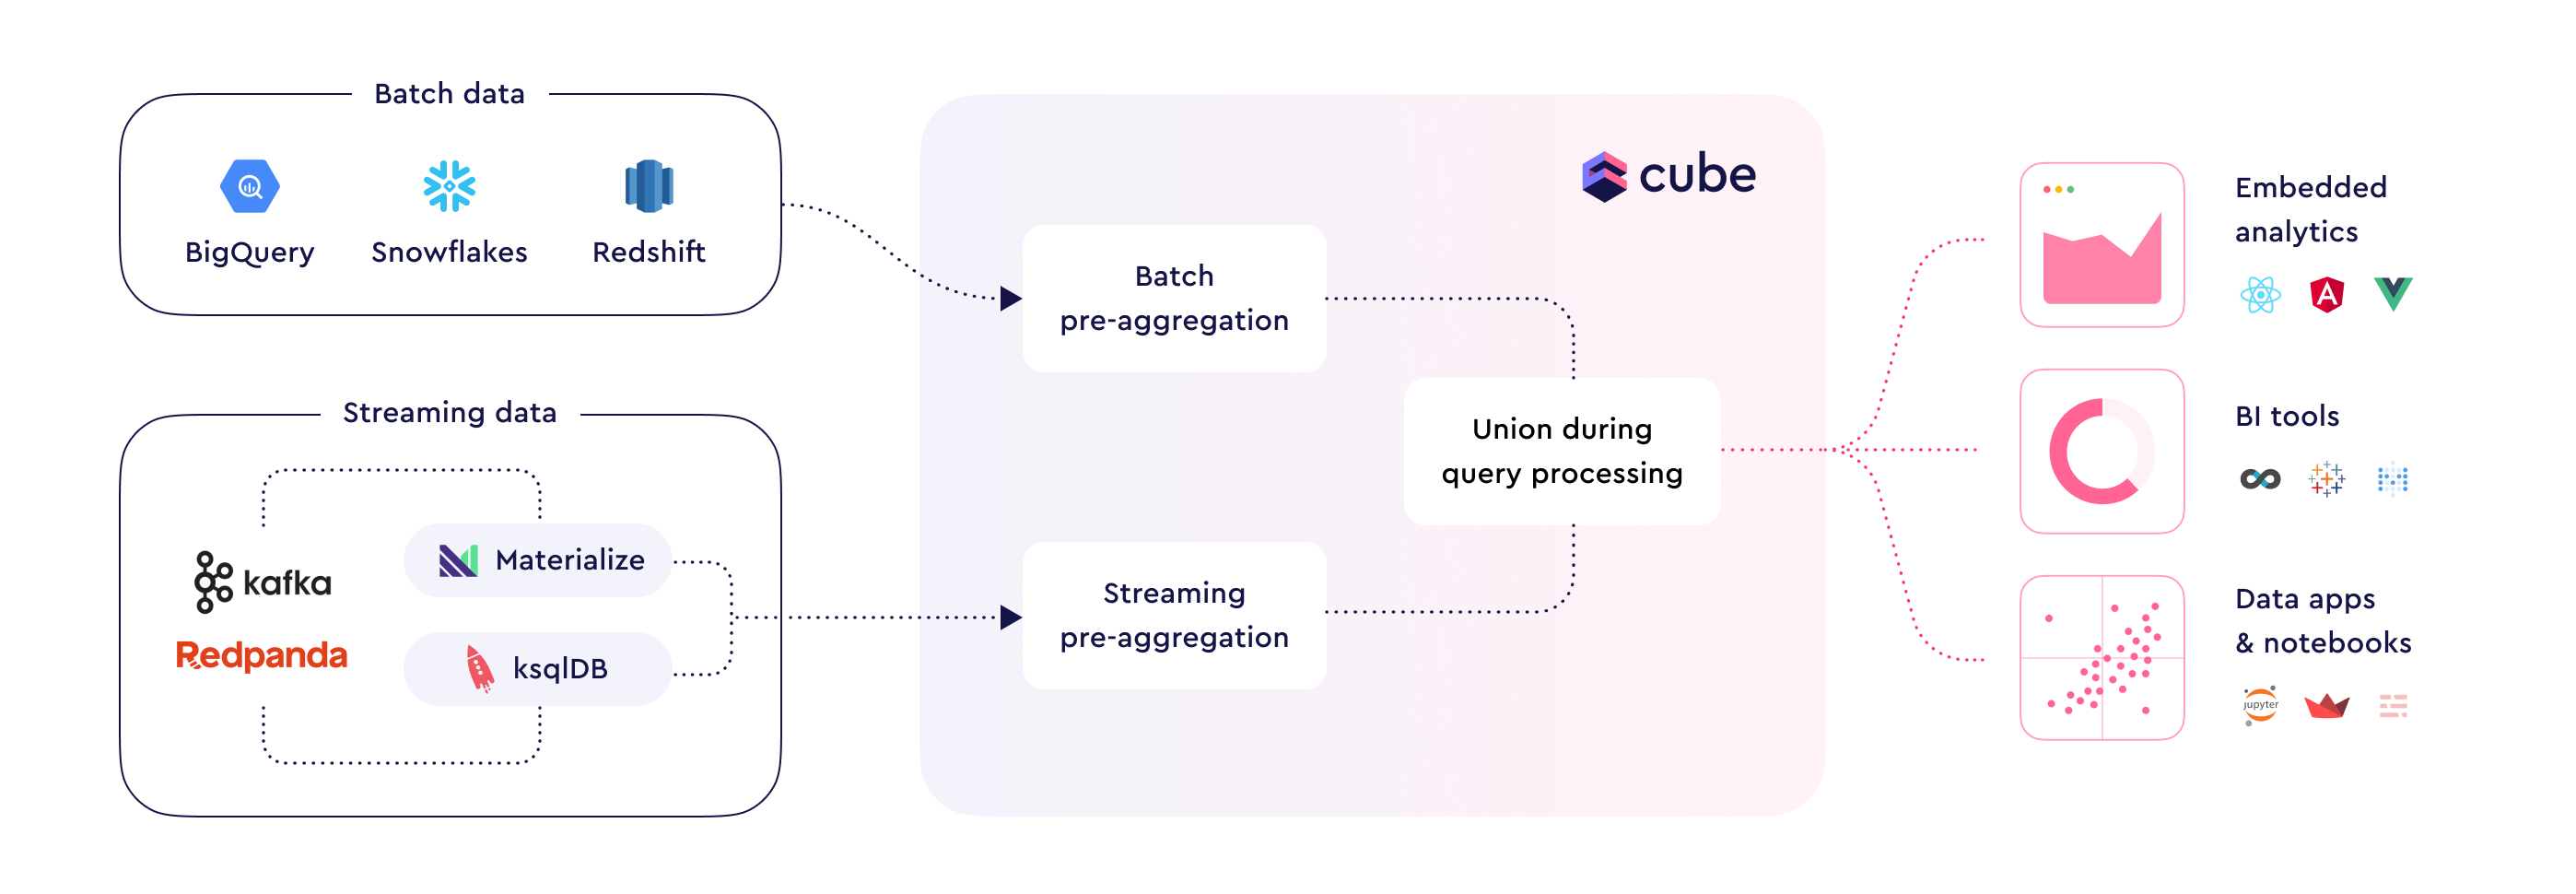
You can use lambda pre-aggregations to combine data from multiple
pre-aggregations, where one pre-aggregation can have batch data and another
streaming.
Cube serves each date range with the first rollup in the list that has a fully
built partition for it. Each next rollup is used only after the last partition
served by the previous one. Partitions of the last rollup are used even if they
are not completely built.
Build ranges of the referenced rollups have to overlap, see
[below](#overlapping-build-ranges).
```yaml title="YAML" theme={null}
cubes:
- name: streaming_users
# This cube uses a streaming SQL data source such as ksqlDB
# ...
pre_aggregations:
- name: streaming
type: rollup
measures:
- CUBE.count
dimensions:
- CUBE.name
time_dimension: CUBE.created_at
granularity: day,
partition_granularity: day
- name: users
# This cube uses a data source such as ClickHouse or BigQuery
# ...
pre_aggregations:
- name: batch_streaming_lambda
type: rollup_lambda
rollups:
- users.batch
- streaming_users.streaming
- name: batch
type: rollup
measures:
- users.count
dimensions:
- users.name
time_dimension: users.created_at
granularity: day
partition_granularity: day
build_range_start:
sql: SELECT '2020-01-01'
build_range_end:
sql: SELECT '2022-05-30'
```
```javascript title="JavaScript" theme={null}
// This cube uses a streaming SQL data source such as ksqlDB
cube("streaming_users", {
// ...
pre_aggregations: {
streaming: {
type: `rollup`,
measures: [CUBE.count],
dimensions: [CUBE.name],
time_dimension: CUBE.created_at,
granularity: `day`,
partition_granularity: `day`
}
}
})
// This cube uses a data source such as ClickHouse or BigQuery
cube("users", {
// ...
pre_aggregations: {
batch_streaming_lambda: {
type: `rollup_lambda`,
rollups: [users.batch, streaming_users.streaming]
},
batch: {
type: `rollup`,
measures: [users.count],
dimensions: [users.name],
time_dimension: users.created_at,
granularity: `day`,
partition_granularity: `day`,
build_range_start: {
sql: `SELECT '2020-01-01'`
},
build_range_end: {
sql: `SELECT '2022-05-30'`
}
}
}
})
```
## Overlapping build ranges
A partition that isn't fully built is skipped for every rollup except the last
one. When the build range of a rollup starts exactly where the previous one ends,
the partition that has just become complete, for example the previous day right
after midnight, is served by no rollup until it's rebuilt. Such days are missing
from query results without an error.
To avoid that, start the build range of each rollup earlier than the build range
of the previous one ends, with a margin longer than the previous rollup's
`refresh_key` interval plus its build time. Rows are not counted twice: a rollup
skips partitions that the previous one already serves.
```yaml title="YAML" theme={null}
cubes:
- name: orders
# ...
pre_aggregations:
- name: lambda
type: rollup_lambda
rollups:
- CUBE.batch
- CUBE.hot
- name: batch
# ...
partition_granularity: day
build_range_end:
sql: SELECT CURRENT_DATE - INTERVAL '14 days'
refresh_key:
every: 1 day
- name: hot
# ...
partition_granularity: day
# Starts 2 days before `batch` ends
build_range_start:
sql: SELECT CURRENT_DATE - INTERVAL '16 days'
build_range_end:
sql: SELECT CURRENT_DATE
refresh_key:
every: 10 minute
```
```javascript title="JavaScript" theme={null}
cube(`orders`, {
// ...
pre_aggregations: {
lambda: {
type: `rollup_lambda`,
rollups: [CUBE.batch, CUBE.hot]
},
batch: {
// ...
partition_granularity: `day`,
build_range_end: {
sql: `SELECT CURRENT_DATE - INTERVAL '14 days'`
},
refresh_key: {
every: `1 day`
}
},
hot: {
// ...
partition_granularity: `day`,
// Starts 2 days before `batch` ends
build_range_start: {
sql: `SELECT CURRENT_DATE - INTERVAL '16 days'`
},
build_range_end: {
sql: `SELECT CURRENT_DATE`
},
refresh_key: {
every: `10 minute`
}
}
}
})
```
If a rollup uses a coarser `partition_granularity` than the next one, the next
rollup has to start before the beginning of the previous rollup's last partition,
because that whole partition is skipped until it's complete. For example, with
`month` partitions on `batch` and `day` partitions on `hot`, start `hot` at
`date_trunc('month', CURRENT_DATE - INTERVAL '16 days')`.
[streaming-pre-agg]: /docs/pre-aggregations/using-pre-aggregations#streaming-pre-aggregations
This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.